
正規化ルールの操作
正規化ルールを操作するための概要と手順。
- 目録管理者
- 目録マネージャー
- 目録編集者
正規化ルールは、たとえば、レコードがメタデータエディターに保存されたとき、インポートプロファイルからインポートされたとき、外部検索リソースからインポートされたとき、またはメタデータエディターの [レコードの拡張] メニューで編集されたときなど、さまざまな段階で書誌メタデータを変更または更新するために使用されます。正規化ルールは特定の構文で記述されているため、レコードへの特定の変更に影響を及ぼすルールを作成できます。たとえば、フィールドを編集または削除する際、書誌レコードに含まれる他の条件または含まれない他の条件に基づいて、条件付きで行うことができます。
Normalization rules can be applied to individual records in the MD Editor or to a group of records:
- To apply normalization rules to an individual record, use the Enhance Record option (refer to the section MD Editor Menu and Toolbar Options) or Apply Changes to an individual record when you preview normalization rules (see To preview the outcome of a rule).
- To apply normalization rules to a set of records, you need to create a process using the MarcDroolNormalization, MarcXSLNormalization or DcDroolNormalization tasks (see Working with Normalization Processes) and specify the normalization rule created with the MD Editor (refer to the procedure To create a new normalization rule file).Once you have created the process, you can run a job using that process (see Running Manual Jobs on Defined Sets).In addition, you can create a process that enables application of normalization rules when selecting Save in the MD Editor (see Working with Normalization Processes).
正規化ルールは、特定のプログラミング構文に従い、MDエディタのルールタブにある編集ウィンドウを使用して作成されます。

独自の正規化ルールプログラムを作成するだけでなく、既存のルールを編集ウィンドウにコピーして貼り付けたり、すぐに使用できるサンプル([ルールタブ])を使用したりすることで、正規化ルールを作成することもできます。See Normalization Rules Syntax for more information regarding the syntax for normalization rules and examples that you can copy to the editing window.
MDエディタのプレビュー機能を使用することで次のことができます。
- 正規化ルールとメタデータレコードを並べて表示
- メタデータレコードで実行した場合のルールの結果のプレビュー
- ルールとプレビューの変更を切り替え
- ルールを編集してすぐにテストする
- For a short overview of Normalization Rules, watch Normalization Rules(6:00).
- For detailed information on Normalization rules with examples, watch Normalization Rules(1 hr).
正規化ルールの作成
This section describes how to create a normalization rule or copy a rule from the Community Zone, work with previously created rules, and preview the rule's outcome when it is run on a single metadata record.For more information, see the Normalization Rules area on this page.
Note that normalization rules on Institution Zone records that are linked to Network Zone records can be applied only to local fields.To apply normalization rules to such records, run the normalization rules and normalization processes only in the Network institution.
For Network Zone consortia members, users can control whether to save new rules locally or in a network institution.To make this selection, open the Records or Templates area and navigate to New > Placement Options.この選択はユーザーごとに行われることに注意してください。
- MDエディタページ([リソース > 目録 > メタデータエディタを開く])で、[ルール]領域を開きます。
- To create a normalization rule for a MARC or Dublin Core record, select New > Normalization.The Normalization Rules Properties (New Rule) dialog box opens.
 正規化ルールのプロパティダイアログボックス
- Enter a name and a description for the normalization rule.
- The word rule must not be capitalized if used in the rule name.If capitalized, the rule does not work.
- ルール名にバックスラッシュ (\) を使用しないでください!Otherwise, the rule cannot be used for the filter set functionality.
- ルール名/説明の文字数制限は255文字です。
- To create a normalization rule for a MARC record, select Drool.To create a normalization rule for a DC (Dublin Core) record, select XSL.
MARC record normalization rules also support XSL.
- Select an access option,Private or Shared.[プライベート] を選択した場合、自分だけがルールを操作でき、ルールを正規化プロセスに含めることはできません。[共有] を選択すると、ルールは目録者間で共有されます。In this case, more than one user can view the rule at the same time; if two or more people have the rule open for editing, a warning message appears when one of you tries to save changes.(変更を保存するか、他のユーザーが変更を行って保存できるようにするかを選択できます。)
- Select Save.The Metadata Editor editing pane opens.You can include existing rule syntax (Edit > Add Rule > {type of rule}) or define a rule (for details, see Normalization Rules Syntax).
- 保存を選択します。ルールは、[正規化ルール]タブのルールファイルのリストに追加されます。
- On the Metadata Editor page (Resources > Cataloging > Open Metadata Editor), select the Rules tab and expand the Normalization folder.
- To copy, open the Community folder, right-click the rule you want to copy and select Duplicate.The Duplicate Rule dialog opens.名前と説明を指定し、プライベート(自分だけが利用可能)として、または共有ルール(組織内のすべてのユーザーが利用可能)として保存するかどうかを指定します。The dialog box indicates the Alma user name and contact email of the user who contributed the rule to the Community Zone.ご質問がある場合は、当該ユーザーに問い合わせてください。
- コミュニティゾーンに独自のルールを投稿するには、ルールを右クリックして [CZに投稿する] を選択します。The Rule Sharing dialog opens.Provide a descriptive name and description, and select Save to save the rule in the Community Zone.
- [MD エディタ] ページ ([リソース] > [目録] > [メタデータ エディタを開く]) で[ルール] タブを選択し、 [正規化] フォルダーを展開して、保存されているルールを表示します。
- 使用するルールを選択し、次のオプションのいずれかから選択します。
- Edit – Opens the text box with the rule(s) syntax, enabling you to modify this syntax (for details, see Normalization Rules Syntax).
- Delete – Select Yes to confirm the rule file's deletion.
- [重複] - 選択したルールファイルを複製し、元のファイルに影響を与えずに新しいルールとして変更して保存できるようにします。
- [プロパティ] - 正規化ルールのプロパティダイアログボックスを開き、ルールファイルのプロパティを変更できます。
- To rename the rule, duplicate the rule, give the duplicate the desired name, and then delete the old rule.
- 作業したい書誌レコードを見つけ([リポジトリ検索] を使用するか、MDエディタの [レコード] タブ内に検索する)、MDエディタで開きます。
- PressF6 or select the Split Editor icon.
- Select the Rules tab in the left pane and expand the Normalization folder.
- Right-select the rule that you want to preview or test in the Private or Shared(not the Community) folder and select Edit.
 The rule is displayed in the Metadata Editor right pane.

- [プレビュー]を選択します。The rule is applied to the record, and the outcome appears.
To update Network records, the normalization must be run by the Network institution (not by a member).An institution cannot update Network records; therefore, the normalization is only applied to local fields (the local extensions of the member).When previewing a rule for a Network record, the following message is displayed:Note that the rules are applied only to local fields when the normalization process is run.
- Select Apply Changes to save the modifications to the record or select Back to normalization rules to continue editing.
- When you have made your final changes to the normalization rule, select Save and test using external record to save the final version of your normalization rule.For details, see Testing Normalization Rules for External Data Sources.
Normalization Rules for Dublin Core and MODS Records
メタデータエディタには、Dublin CoreとMODSに関連する次のタイプのルールがあります。
- XSL表示ルール
- XSL 正規化ルール
XSL Normalization Rule does not support discovery:local.
Dublin Core and MODS normalization rules cannot be written in a regular Normalization Rule format, but only as an XSL.This means that you compose the XSL directly in the Metadata Editor (as explained above), or you can compose it in Notepad (or another external application of your choice) and then copy it to the Metadata Editor.
You can view the below examples of XSL Normalization Rules for Dublin Core in the Community Zone in the Metadata Editor:
- EXL – dc:language値「en」を「English」に変更
- EXL – Dublin Coreレコードの文字列を置き換える一般的なルール
- EXL_Add_field_accessRights
- 選択した外部アプリケーションでXSLを記述します。
- Open the Metadata Editor > Rules section.
- Copy and paste the XSL to the Metadata Editor and save the rule.
Primo VEの正規化ルールプロセス構成
In addition to Alma normalization rules, you can create normalization rules for Primo VE and Esploro.To create these rules, select New, and then select:
-
Normalization (Discovery) – This option appears only when Primo VE is defined in the system.Select this option if you are creating DC or XML normalization rules for bibliographic records that are loaded into Primo VE and not managed in Alma.For information regarding the syntax of these rules, see Normalization Rule Syntax for DC and XML Formats.
-
Normalization (Research) – This option appears only when Esploro is defined in the system.For details, see Managing Asset Normalization Rules(Esploro).
正規化ルールの構文
ルールには、1つ以上の他のルールを含めることができます。各ルールには、条件とレコードに適用される1つ以上のアクションが含まれています。レコードが条件を満たしている場合、アクションはレコードに適用されます。Each action can be performed on a single field within a record.アクションはルール内に表示されている順序で実行されます。
複数のルールを含むルールを定義する場合、優先度(または重要度)係数を使用する必要があります。優先度の高いルールで規定されているアクションが最初に実行されます。たとえば、優先度2のルールのアクションは、優先度1のルールのアクションの前に実行されます。For examples of the way in which priority (or salience) can be used in normalization rules, see Alma Normalization Rule Examples.Note that priority (or salience) is only necessary when the fields in the rules are the same.Otherwise, when each rule deals with different fields, multiple rules are performed from top to bottom.
Learn how to create normalization rules that delete specified fields from records, or change the contents of these fields in the Normalization Routine Syntax for Deletion or Content Change video (9:57 mins).
<conditions on MARC record>には、レコードに適用される1つ以上のブール句が含まれています。<conditions on MARC record>がTRUEを返す場合、ルールはレコードに適用されます。 そうでない場合、ルールは適用されず、レコードは処理されません。
- “When” が最初の行の唯一の単語である必要があります。条件は別の行に配置する必要があります。
- “When”という条件のみで、レコード全体に複数の条件を使うことができます。
- ルールに複数のブール演算子を含めることはできますが、多数のブール演算子を選択すると、パフォーマンスが低下する可能性があります。したがって、ブール演算子は各ルールあたり200個以下に収める必要があります。
- 指定しない場合、条件はレコードレベルで機能します。各MARC21フィールドに個別に条件を適用したい場合は、フィールドごとに条件を指定する必要があります。たとえば、同じタグを持つMARC21フィールドが複数ある場合などです。
正規化ルールにおけるエスケープ文字の理解
正規化ルールを作成する際、引用符、タブ、バックスラッシュなどの特殊文字を含める必要がある場合があります。これを正しく行うには、エスケープ文字を使用します。エスケープ文字とは、システムにこれらの記号をどのように解釈するかを伝える特別な組み合わせです。
有効なエスケープシーケンス
Almaは以下のエスケープシーケンスを認識します。
- \\b - バックスペース
- \t - tab
- \n - new line
- \f - フォームフィード
- \r - carriage return
- \" - ダブルクォート
- \' - シングルクォート
- \\ - バックスラッシュ
これらのシーケンスは、有効な文字の前にバックスラッシュ1つで始まらなければなりません。
避けるべきよくある間違い
バックスラッシュの数が間違っているとエラーの原因になります。例:
- \zや\\\zは無効であり、エラーが発生します。
- 有効なエスケープ文字を伴わない単独のバックスラッシュ(\)も無効です。
エラーの修正方法
次のようなエラーが表示された場合:
"Invalid escape sequence (valid ones are \b \t \n \f \r "'\)"
バックスラッシュを調整することで修正できます。例:
- replacing \\\ with \\
- replacing \. with .
- replacing \( with ( and \) with )
- replacing \\\| with \\|
これらの変更により、構文エラーを回避しつつルールの意図した動作を維持できます。
レコード要素
条件とアクションは、MARCレコード、フィールド(1つ以上)、インジケーター、サブフィールド(1つ以上)、フィールド/サブフィールドの内容などのレコード要素に適用されます。
条件をテストしたり、レコード要素にアクションを適用したりするには、要素が次の構文に一致する必要があります。
| 表現 | 意味 |
|---|---|
| "<tag>"、"<new tag>" | 001、245などのフィールドタグを表しています。 |
| "<oldCode>"、"<newCode>" | a、b、cなどのサブフィールドコードを表しています。 |
| "<element>" データフィールドの場合 | データフィールドに指定できる値は次のとおりです
|
| "<element>" (コントロールフィールド) | 以下は、コントロールフィールドに使用できる値です
|
| "<element>"固定位置フィールドの場合 |
The following are the possible values for a fixed position UNIMARC/CNMARC 1XX field:
Relevant only for UNIMARC/CNMARC 1XX fields. |
| CONDITION(レコードレベル) | 可能な条件オプションは次のとおりです。See the next section (Conditions) for important information.
The following are the possible condition options relevant only for UNIMARC/CNMARC 1XX fields:
|
条件
条件は、ルールレベル全体(WHEN)、または特定のアクションレベル(IF)で定義できます。同じ条件でも定義されているレベルによって異なる動作をします。
- WHEN句 – ルールがレコードに適用されるかどうかを判断するために、レコード全体で満たされる必要がある条件です
- IF(within an action) – A condition that applies to a single field in order to determine whether the specific action is taken on that field
条件は次のとおりです
-
containsScript – Use this condition to detect a specific language.The containsScript condition uses the following fixed list of languages for which you can check: Arabic, Armenian, Bengali, Bopomofo, Braille, Buhid, Canadian_Aboriginal, Cherokee, Cyrillic, Devanagari, Ethiopic, Georgian, Greek, Gujarati, Gurmukhi, Han, Hangul, Hanunoo, Hebrew, Hiragana, Inherited, Kannada, Katakana, Khmer, Lao, Latin, Limbu, Malayalam, Mongolian, Myanmar, Ogham, Oriya, Runic, Sinhala, Syriac, Tagalog, Tagbanwa, TaiLe, Tamil, Telugu, Thaana, Thai, Tibetan, and Yi.次の構文例を参照してくださいrule "Is CJK in Authority" when containsScript "Han" "1**" then set indication."true" end
- exists <element> – 少なくとも1つの一致が見つかりました
- exists <element> – データフィールドに適用されます。IF句で使用する場合、アクション要素と条件によってテストされる要素の両方が同じ(データ)フィールドでなければなりません。
- existsControl <element> - コントロールフィールドに適用されます。IF句で使用する場合、アクション要素と条件によってテストされる要素の両方が同じ(コントロール)フィールドでなければなりません。
- existsMoreThanOnce <element> – 複数の一致が見つかりました。データフィールドに適用されます。IF句で使用する場合、アクション要素と条件によってテストされる要素の両方が同じ(データ)フィールドでなければなりません。
- not exists <element> – 一致するものは見つかりませんでした
- not exists <element> – データフィールドに適用されます。IF句で使用する場合、アクション要素と条件によってテストされる要素の両方が同じ(データ)フィールドでなければなりません。
- not existsControl <element> – コントロールフィールドに適用されます。IF句で使用する場合、アクション要素と条件によってテストされる要素の両方が同じ(コントロール)フィールドでなければなりません。
-
recordHasDuplicateSubfields(for indication rules; see Working with Indication Rules) – Returns true if duplicate subfields (subfield and its contents) are found for the current record according to the fields, subfields, and the characters to ignore (charsToIgnore) string that were passed as parameters in the following format:recordHasDuplicateSubfields "<tag>" "<code>" "<charsToIgnore>"コンマで区切られた複数のタグ(フィールド)を指定することができます。複数のコード(サブフィールド)をスペースなしで指定して、それらを区切ることができます。One or more characters (alphanumeric or punctuation) with no spaces to separate them can be specified as characters to ignore at the end of the content in the subfields that are being evaluated for duplication.See Example 6 for more information.For the records that meet the recordHasDuplicateSubfields condition (returns true), a set of the records is created.
各IF句のアクションには、次のいずれかの形式を使用することができます
- Applies if a specific condition is not true, for example:addControlField "{element}"if(not exists "{condition}")
- Applies if a specific condition is true, for example:addControlField "{element}"if(exists "{condition}")
- Applies unconditionally, for example:addControlField "{element}"
The Boolean OR operator can be used in a consequence statement by using the pipe (|) symbol, for example:removeField "866" if (not exists "866.8.0 | 99".If the pipe symbol is part of the value, use four backslashes (\\\\) to escape it, for example:removeField "866" if (exists "866.8.0 \\\\| 99")
The if (exists...) condition is met if the value in the condition appears somewhere in the record.このルールを使用して、特定の値を持つサブフィールドをコピー/削除することはできません。特定の値を持つサブフィールドを削除またはコピーするには、XSL 変換ルールを使用します。
アクションリスト
次の表は使用可能なアクションのリストです。
| アクション | フォーマット/例 | コメント |
|---|---|---|
| フィールドとサブフィールドを他のフィールドとサブフィールドに置換 | changeControlField "<tag>" to "<new tag>"
Example:changeControlField "007" to "008"
|
コントロールフィールドのタグ識別子を変更します。内容を変更しません。 |
| changeField "<tag>" to "<new tag>"
Example:changeField "245" to "246"
|
タグ識別子を変更します。この時、インジケータまたはサブフィールドは変更しません。 | |
| changeSubField "<tag>.<code>" to "<new code>"
changeSubFieldOnlyFirst "<tag>.<code>" to "<new code>"
changeSubFieldExceptFirst "<tag>.<code>" to "<new code>"
Example:changeSubField "035.b" to "a"
|
サブフィールド(最初のサブフィールドのみ、もしくは最初のサブフィールド以外のすべて)の"<code>"を、フィールド"<tag>"のサブフィールド"<new code>"に変更します。 | |
| changeFirstIndicator "<tag>" to "<value>"
changeSecondIndicator "<tag>" to "<value>"
Example:changeFirstIndicator "245" to "3"
|
タグ<tag>の指定されたインジケーターの値を設定します。 | |
| combineFields "<tag>" excluding "<comma-separated subfield list>"
Example:combineFields "852" excluding "a,b"
|
指定した番号のすべてのフィールドを統合します。名前付きサブフィールドを除く、2行目以降のすべてのサブフィールドを最初の行にコピーします。除外されたサブフィールドの最初の出現のみがコピーされ、それらが最初の行にまだ存在しない場合のみ適用できます。 | |
| フィールドとサブフィールドの追加 | addField "<tag>.<code>.<value>"
addField "<tag>.{<ind1>,<ind2>}.<code>.<value>"
Example:addField "999.a.RESTRICTED"
|
MARCレコードにフィールドを追加します。サブフィールドの値を指定された値に設定します。 |
| addControlField "<tag>.<value>"
Example:addControlField "008.820305s1991####nyu###########001#0#eng##"
|
MARCレコードにコントロールフィールドを追加します。 | |
| addSubField "<tag>.<code>.<value>"
addSubField "<tag>.{<ind1>,<ind2>}.<code>.<value>"
Example:addSubField "245.h.[Journal]"
|
値<value>を持つサブフィールド<code>をフィールド<tag>に追加します。フィールドが存在しない場合、何も行われません。 | |
| addSystemNumber "<element>" from "<tag>" prefixed by "<prefix tag>"
Example:addSystemNumber "035.a" from "001" prefixed by "003"
|
データフィールド<element>を、括弧内の2番目のコントロールフィールド <prefix tag>の内容と等しくし、その後に最初のコントロールフィールド<tag>の内容を続けます。
たとえば、001の値が9945110100121で、003の値がDAVである場合、左側の例の条件は値が‡(DAV)9945110100121の035を生成します。
|
|
| フィールドをコピー | copyField "<tag>" to "<new tag>"
copyField "<tag>.<code>" to "<new tag>.<new code>"
copyField "<tag>" to "<new tag>.{<ind1>,<ind2>}"
Example:copyField "971.a" to "100.u"
|
フィールドを別のフィールドにコピーします。最初のバージョンでは、サブフィールドは指定されておらず(<code>および<new code>)、新しいフィールドには古いフィールドと同じサブフィールドが含まれています。2番目のバージョンでは、<new code>が指定されていない場合、新しいサブフィールドは<code>で指定されたサブフィールドと同じです。
copyFieldは、既存のフィールドに追加するのではなく、個別のフィールドを作成します。新しいフィールドを既存のフィールドと組み合わせることもできます(combinedFieldsを参照)。 |
| フィールドとサブフィールドを削除 | removeControlField "<tag>"
Example:removeControlField "009"
|
コントロールフィールドのすべての出現を削除します。
コントロールフィールド008を削除し再作成しない場合、Almaはすぐに再作成することに注意してください。フィールドを削除した後に再度追加することを検討してください。例: rule "remove 008" when (TRUE) then removeControlField "008" addControlField "008.######s2013####xx######r#####000#0#eng#d" end |
| removeField"<tag>"
Example:removeField "880"
|
フィールドのすべての出現を削除します<tag>. | |
| removeSubField "<tag>.<code>"
Example:removeSubField "245.h"
|
指定されたフィールドからサブフィールド<code>のすべての出現を削除します。 | |
| フィールドまたはサブフィールドのテキストを置換 | replaceControlContents "<tag>.{<position>,<length>}.<value>" with "<new value>"
Example:replaceControlContents"LDR.{7,1}.s" with "m"
|
コントロールフィールド<tag>の開始位置<position>から<position>+<length>の<value>を"<new value>"に置き換えます。<value>に一致するテキストのみを置き換えます。 |
| replaceContents "<tag>.<code>.<value>" with "<new value>"
replaceContentsOnlyFirst "<tag>.<code>.<value>" with "<new value>"
replaceContentsExceptFirst "<tag>.<code>.<value>" with "<new value>"
Example:replaceContents"245.h.[Journal]" with "[Book]"
|
フィールド"<tag>"のサブフィールド<code>内の<value>と一致する文字列(もしくは最初が一致するサブフィールドの一致する文字列の全インスタンス、または最初が一致するサブフィールドを除いた、全一致するサブフィールドの全一致する文字列)を"<new value>"に置き換えます。<value>と一致しない文字列または文字列の一部は変更されません。 | |
| replaceSubFieldContents "<tag>.<code>" with "<tag>.<code>"
Example:replaceSubFieldContents "245.b" with "100.a"
|
サブフィールドの内容を別のサブフィールドの内容に置き換えます。 | |
|
replaceFixedContents "<tag>.{<1_ind>,<2_ind>}.<code>.{<position>,<length>}.<value>" with "<new value>" Example:replaceFixedContents "100.{1,2}.a.{0,8}.20150226" with "20220724" |
Replaces <value> with <new value> in UNIMARC and CNMARC 1XX fixed position fields. Relevant only for UNIMARC/CNMARC 1XX fields. |
|
| サブフィールドにテキストを追加する | prefix "<tag>.<code>" with "<value>"
Example:prefix "035.b" with "(OCoLC)"
|
フィールド "<tag>"のサブフィールド "<code>" の値に接頭語を追加します。
新しい値<value>の後に、古い値が続きます。 |
| prefixSubField "<tag>.<code>" with "<source tag>.<source code>"
Example:prefixSubField "910.a" with "906.a"
|
フィールド"<source tag>"のサブフィールド"<source code>"の値を、サブフィールド"<code>"の接頭語としてフィールド"<tag>"に追加します。
新しい値は、フィールド"<source tag>"のサブフィールド"<source code>"の値と続き、その後に古い値が続きます。 |
|
| suffix "<tag>.<code>" with "<value>"
Example:suffix "035.b" with "(OCoLC)"
|
フィールド"<tag>"のサブフィールド"<code>" の値に接尾語を追加します。
新しい値<value>の後に、古い値が続きます。 |
|
| suffixSubField "<tag>.<code>" with "<source tag>.<source code>"
Example:suffixSubField "910.a" with "907.c"
|
フィールド"<source tag>"のサブフィールド"<source code>"の値を、フィールド "<tag>"のサブフィールド "<code>"の接尾語として追加します。
新しい値は、フィールド"<source tag>"のサブフィールド"<source code>"の値と続き、その後に古い値が続きます。 |
|
| 書誌および典拠レコードにおける機関情報の維持
たとえば、この構文は、保存時にネットワークゾーンの書誌レコードを正規化するために、[MARC 21書誌メタデータ設定タスクリスト]で選択される正規化ルールで使用できます。 この機能は現在作業中です。この構文を有効にするには、Ex Librisサポートにお問い合わせください。 |
addCreatingAgency "<tag>.<code>"
Example:addCreatingAgency "040.a"
|
作成機関のISILコードを、フィールド"<tag>"のサブフィールド"<code>"に追加します。 |
| addModifyingAgency "<tag>.<code>"
Example:addModifyingAgency "040.d"
|
フィールド "<tag>"のサブフィールド"<code>"に変更する機関ISILコードを追加します。"<tag>.<code>"に既に変更する機関がある場合、これによって別の機関ISILコードが追加されます。 | |
| replaceModifyingAgency "<tag>.<code>"
Example:replaceModifyingAgency "040.d"
|
フィールド "<tag>"のサブフィールド"<code>"に変更する機関ISILコードを追加します。"<tag>.<code>"に変更する機関が既に存在する場合、すべて置き換えられます。 | |
| サブフィールドの分割 | splitSubField "<tag>.{ind1,ind2}.<code>.<delimiter>" to "<tag>.{<ind1>,<ind2>}.<code>" addSeq "<code>"
Example 1:splitSubField "866.a.;" to "555.{0,0}.a" addSeq "8"
Example 2:splitSubField "555.a.– " to "859.{0,0}.a" addSeq "8"
Example 3:splitSubField "859.a.\\\\."
Example 4:splitSubField "999.a.;" to "555.a" addSeq "8"
|
このタグは必須です。
インジケータは任意です。 分割はサブフィールドレベルで行われるため、コードは必須です。 区切り文字には任意の文字列を使用することができます。区切り文字が存在しない場合、完全なサブフィールドが最初の(そして唯一の)発生セグメントとしてコピーされ、シーケンスが追加されます。 toコンポーネントは任意です。指定されている場合、to tag.codeが複数発生し、それぞれに区切り文字までのデータが含まれます。例1および例2を参照してください。toコンポーネントが指定されていない場合、サブフィールドは例3に示されるように、同じフィールド内の同じ内容の追加のサブフィールドとして分割されます。 addSeqコンポーネントは任意です。toコンポーネントが指定されていない場合は関係ありません。addSeqを指定すると、例1のように、シーケンスを持つサブフィールドが追加されます。また、サブフィールドが元のフィールドに既に存在する場合、例2のように、シーケンス(ピリオドが前に付く)がそのフィールドに追加されます。 |
|
重複サブフィールドを削除 |
correctDuplicateSubfields "<tag>" "<code>" 例: Removes duplicate subfields x, y and z from fields 610 and 630. rule "Remove duplicates" priority 1 when (TRUE) then correctDuplicateSubfields "610,630" "xyz" end |
Corrects duplicate subfields (for instance, subfields with the same code AND the same value) by keeping the first occurrence and removing the others from the current record according to the fields and subfields that were passed as parameters. You may want to use recordHasDuplicateSubfields to create the set that you supply to your normalization rule that uses correctDuplicateSubfields.See Example 6 for more information. For deduplication of subfields with different values, see:How to remove all but one of several similar subfields in the same field in MD Editor. |
|
移動サブフィールド |
moveSubfieldsToEndOfField "<tag>" "<code>" 例: Moves subfields 9 and 2 to the end of field 650. rule "Move subfields to end of field" priority 1 when (TRUE) then moveSubfieldsToEndOfField "650" "92" end |
各サブフィールドの最初の出現をフィールドの末尾に移動させ、他に出現する同じサブフィールドをすべて削除します。 複数のサブフィールドが指定されている場合、ルールで識別されているのと同じ順序で最後に配置されます。この例では、サブフィールド9が末尾に配置され、その後にサブフィールド2が続いています。 Note that the if statement is not supported with the moveSubfieldsToEndOfField action. |
|
現在のレコードの重複するフィールドを修正する |
correctDuplicateFields "{fields}" 例: correctDuplicateFields "610,630,650" |
このアクションが取り入れるパラメーターは、610,630,650などのコンマ区切りのフィールド値を含むフィールドのみです。 このアクションは、パラメーターとして渡されたフィールドに従って、現在のレコードの重複したフィールドを修正します。 このアクションは、同じフィールドの複数のインスタンス間で見つかった重複データを識別して修正するためにのみ使用できます。 |
|
重複したフィールドを見つける (Indication Rules; see Working with Indication Rules) |
recordHasDuplicateFields "{fields}" 例: recordHasDuplicateFields "610,630,650" |
このアクションが取り入れるパラメーターは、610,630,650などのコンマ区切りのフィールド値を含むフィールドのみです。 このアクションの結果は、trueまたはfalseのいずれかです。パラメーターとして渡されたフィールドに従って、現在のレコードに重複したフィールドが見つかった場合、trueを返します。 このアクションは、同じフィールドの複数のインスタンス間で見つかった重複データを識別して修正するためにのみ使用できます。 |
ワイルドカードと特殊文字
While the use of regular expressions in Alma Normalization Rules is not currently fully supported, some regular expressions can be used – for examples of these, see Alma Normalization Rule Examples.
サブフィールド区切り文字($$)は、ルール名を含め、ルール内のどこにも表示することはできません。
行の先頭にあるハッシュ文字(#)は、行の残りがコメントであることを示し、ルールの処理時には無視されます。
The hash character (#) is not treated as a space by the normalization rules function replaceControlContents. The hash (#) is not a wild card and is not supported by this function.
アスタリスク(*)は、長さゼロの文字列を含む任意の文字列と一致させるために使用されます。For example,"<tag>.<*>.<value>" applies to all the subfields in the tag <tag> that have the value <value>.* is "greedy", so it matches as many characters as possible in the string.例:文字列が「a b c b d b e」の場合、「b*b」というパターンは「b c b」だけでなく、「b c b d b」も一致します。
空のインジケータ(フィールドまたはサブフィールドは除く)は、ハイフン(-)で示されます。For example,"<tag> {-,<ind2>}" returns all the fields where the MARC tag is <tag>, the first indicator is not defined, and the second indicator is <ind2>.
サブフィールドのテキストに最後の文字としてピリオドが含まれる場合、4つのバックスラッシュ記号を使用してピリオドに一致させます。例:
二重引用符は条件(のみ)で使用できます。条件の一部として二重引用符を使用するには、二重引用符(")ではなく、単一引用符を使用してルール内のテキストを囲みます(')。この方法を使用すれば、二重バックスラッシュ(\\)に続くテキスト内で二重引用符を使用できます。
ヘブライ語の日付は、条件(のみ)で使用できます。(ヘブライ語は右から左に読み取るため、次の例の二重バックスラッシュは実際には二重引用符の前にあります。)
- ワイルドカードは、条件または値の最初の文字として使用することはできません。
- To use a literal backslash (\), escape it with another backslash:\\.
- ピリオドが文字列の最後の文字である場合、4つのバックスラッシュ (\\\\)を使用してエスケープします。ピリオドの直後に別の文字が続く場合、4つのバックスラッシュは必要ありません(次の例のようにaddField "907.a.F.L.T\\\\.")。ただし、一貫性のある望ましい結果を確保するには、正規化ルールで常に4つのバックスラッシュを使用することをお勧めします。次の例を参照してください。
- 上記のように、二重引用符が単一引用符を使用してエスケープする条件(でのみ)使用される場合や、単一引用符を使用してエスケープする条件で単一引用符を使用する場合、二重引用符または引用符をダブルバックスラッシュでさらにエスケープする必要があります。
- If the pipe symbol is part of the condition, use four backslashes to escape it, for example:removeField "866" if (exists "866.8.0\\\\|99").これは、条件でパイプ記号を使用する場合にのみ必要です。
例:replaceContentsを使用した正規化ルールでのピリオドの使用
ピリオドを含むレコードの例:
245 00 $$a Feminist literary theory.: $$b a reader / $$c edited by Mary Eagleton.
246 0# $$a F.L.T.
上記のサンプルレコードの正規化ルール
前後の例については、下の図を参照してください。
例:addFieldを使用した正規化ルールでのピリオドの使用
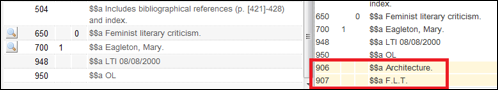
以下は、ピリオドを追加する必要のあるレコードの例です。
906 $$a Architecture.
907 $$a F.L.T.
以下は、常にスラッシュを含めるというベストプラクティスを使用した上記のサンプルレコードの正規化ルールです:
レコードの前後の例については、次の図を参照してください。
正規化ルールの例
For a list of over 100 normalization rule examples and other normalization rule documents, see Alma Normalization Rule Examples.
For more information on creating normalization rules for bibliographic records in XSL format, see Alma XSL Normalization Rule Examples.
Alma は XSL バージョン 3.0 までをサポートします。
Page tags: article:topicproduct:almacontent:Documentationlang:englishactionsRulesyntaxnormalization rule syntaxconditionselements
