
Trabajar con reglas de normalización
Overview and instructions for working with normalization rules.
- Administrador de catalogación
- Gerente de catálogo
- Catalogador
Las reglas de normalización se utilizan para cambiar o actualizar los metadatos bibliográficos en diversas etapas, por ejemplo, cuando el registro se guarda en el Editor de metadatos, se importa utilizando el perfil de importación, se importa desde un recurso de búsqueda externo o se edita utilizando el menú "Mejorar el registro" del Editor de metadatos. Las reglas de normalización se escriben con una sintaxis específica, lo que permite crear reglas que afecten cambios específicos en los registros. Por ejemplo, puede editar o borrar campos, y también puede hacerlo de forma condicional, basándose en una condición que se da en el registro bibliográfico.
Normalization rules can be applied to individual records in the MD Editor or to a group of records:
- To apply normalization rules to an individual record, use the Enhance Record option (refer to the section MD Editor Menu and Toolbar Options) or Apply Changes to an individual record when you preview normalization rules (see To preview the outcome of a rule).
- To apply normalization rules to a set of records, you need to create a process using the MarcDroolNormalization, MarcXSLNormalization or DcDroolNormalization tasks (see Working with Normalization Processes) and specify the normalization rule created with the MD Editor (refer to the procedure To create a new normalization rule file). Once you have created the process, you can run a job using that process (see Running Manual Jobs on Defined Sets). In addition, you can create a process that enables application of normalization rules when selecting Save in the MD Editor (see Working with Normalization Processes).
Normalization rules are created by following a specific programming syntax and using the editing window provided in the MD Editor under the Rules tab.

In addition to creating your own normalization rules program, you can also copy/paste existing rules into the editing window or use out-of-the-box examples (Rules tab) to develop your normalization rules. See Normalization Rules Syntax for more information regarding the syntax for normalization rules and examples that you can copy to the editing window.
Al usar la función Vista preliminar en el Editor MD, se puede:
- Ver las reglas de normalización y los registros de metadatos unos junto a otros
- Tener una vista preliminar del resultado de una regla al ejecutarla en un registro de metadatos
- Alternar entre la regla y los cambios de la vista preliminar
- Editar reglas y probarlas de inmediato
- For a short overview of Normalization Rules, watch Normalization Rules(6:00).
- For detailed information on Normalization rules with examples, watch Normalization Rules(1 hr).
Crear Reglas de normalización
This section describes how to create a normalization rule or copy a rule from the Community Zone, work with previously created rules, and preview the rule's outcome when it is run on a single metadata record. For more information, see the Normalization Rules area on this page.
Note that normalization rules on Institution Zone records that are linked to Network Zone records can be applied only to local fields. To apply normalization rules to such records, run the normalization rules and normalization processes only in the Network institution.
For Network Zone consortia members, users can control whether to save new rules locally or in a network institution. To make this selection, open the Records or Templates area and navigate to New > Placement Options. Téngase en cuenta que esta selección es por usuario.
- On the MD Editor page (Resources > Cataloging > Open Metadata Editor), open the Rules area.
- To create a normalization rule for a MARC or Dublin Core record, select New > Normalization. The Normalization Rules Properties (New Rule) dialog box opens.
 Cuadro de diálogo Propiedades de reglas de normalización
- Enter a name and a description for the normalization rule.
- The word rule must not be capitalized if used in the rule name. If capitalized, the rule does not work.
- ¡No use una barra diagonal invertida en el nombre de una regla! Otherwise, the rule cannot be used for the filter set functionality.
- El límite de caracteres para los nombres y descripciones de las reglas es de 255 caracteres.
- To create a normalization rule for a MARC record, select Drool. To create a normalization rule for a DC (Dublin Core) record, select XSL.
MARC record normalization rules also support XSL.
- Select an access option,Private or Shared. If you select Private, only you can work on the rule, and the rule cannot be included in a normalization process. If you select Shared, your rule is shared among catalogers. In this case, more than one user can view the rule at the same time; if two or more people have the rule open for editing, a warning message appears when one of you tries to save changes. (Existe la opción de conservar los cambios propios o permitir que el otro usuario realice y guarde sus propios cambios.)
- Select Save.The Metadata Editor editing pane opens. You can include existing rule syntax (Edit > Add Rule > {type of rule}) or define a rule (for details, see Normalization Rules Syntax).
- Select Save. The rule is added to the list of rule files under the Normalization Rules tab.
- On the Metadata Editor page (Resources > Cataloging > Open Metadata Editor), select the Rules tab and expand the Normalization folder.
- To copy, open the Community folder, right-click the rule you want to copy and select Duplicate. The Duplicate Rule dialog opens. Introduzca su nombre y descripción, e indique si se desea guardar como regla privada (disponible sobre para usted) o compartida (disponible para todos los usuarios en su institución). The dialog box indicates the Alma user name and contact email of the user who contributed the rule to the Community Zone. Si tiene alguna pregunta, puede contactar a este usuario.
- To contribute your own rule to the Community Zone, right-click the rule and select Contribute to CZ. The Rule Sharing dialog opens. Provide a descriptive name and description, and select Save to save the rule in the Community Zone.
- On the Metadata Editor page (Resources > Cataloging > Open Metadata Editor), select the Rules tab and expand the Normalization folder to display the saved rules.
- Seleccionar la regla con la que se desea trabajar y seleccionar una de las siguientes opciones:
- Edit – Opens the text box with the rule(s) syntax, enabling you to modify this syntax (for details, see Normalization Rules Syntax).
- Delete – Select Yes to confirm the rule file's deletion.
- Duplicate – Duplicates the selected rule file, enabling you to modify and save it as a new rule without affecting the original file.
- Properties – Opens the Normalization Rules Properties dialog box, enabling you to modify the properties of the rule file.
- To rename the rule, duplicate the rule, give the duplicate the desired name, and then delete the old rule.
- Locate the bibliographic record with which you want to work (using the Repository Search or within the MD Editor > Records tab) and open it in the Metadata Editor.
- PressF6 or select the Split Editor icon.
- Select the Rules tab in the left pane and expand the Normalization folder.
- Right-select the rule that you want to preview or test in the Private or Shared(not the Community) folder and select Edit.
 The rule is displayed in the Metadata Editor right pane.

- Select Preview. The rule is applied to the record, and the outcome appears.
To update Network records, the normalization must be run by the Network institution (not by a member). An institution cannot update Network records; therefore, the normalization is only applied to local fields (the local extensions of the member). When previewing a rule for a Network record, the following message is displayed:Note that the rules are applied only to local fields when the normalization process is run.
- Select Apply Changes to save the modifications to the record or select Back to normalization rules to continue editing.
- When you have made your final changes to the normalization rule, select Save and test using external record to save the final version of your normalization rule.For details, see Testing Normalization Rules for External Data Sources.
Normalization Rules for Dublin Core and MODS Records
En el Editor de metadatos, existen los siguientes tipos de reglas relacionadas con Dublin Core y MODS:
- Reglas de indicación XSL
- XSL normalization rule
XSL Normalization Rule does not support discovery:local.
Dublin Core and MODS normalization rules cannot be written in a regular Normalization Rule format, but only as an XSL. This means that you compose the XSL directly in the Metadata Editor (as explained above), or you can compose it in Notepad (or another external application of your choice) and then copy it to the Metadata Editor.
You can view the below examples of XSL Normalization Rules for Dublin Core in the Community Zone in the Metadata Editor:
- EXL: Cambiar el valor dc:language en a Inglés
- EXL: Regla genérica que reemplaza la secuencia en el registro Dublin Core
- EXL_Add_field_accessRights
- Escribir el XSL en la aplicación externa que se elija.
- Open the Metadata Editor > Rules section.
- Copy and paste the XSL to the Metadata Editor and save the rule.
Reglas de normalización para Primo VE y Esploro.
In addition to Alma normalization rules, you can create normalization rules for Primo VE and Esploro. To create these rules, select New, and then select:
-
Normalization (Discovery) – This option appears only when Primo VE is defined in the system. Select this option if you are creating DC or XML normalization rules for bibliographic records that are loaded into Primo VE and not managed in Alma. For information regarding the syntax of these rules, see Normalization Rule Syntax for DC and XML Formats.
-
Normalization (Research) – This option appears only when Esploro is defined in the system. For details, see Managing Asset Normalization Rules(Esploro).
Normalization Rule Syntax
La regla puede contener una o varias reglas. Cada regla contiene una condición y una o más acciones para aplicar a los registros. Las acciones se aplican a un registro si el registro cumple con la condición. Each action can be performed on a single field within a record. Las acciones se llevan a cabo en el orden en que aparecen en la regla.
Al definir una regla que contenga reglas múltiples, se debe usar el factor de prioridad (o prominencia). Las acciones estipuladas en la regla con prioridad más alta se ejecutan primero. Por ejemplo, la acción de una regla con prioridad 2 se ejecuta antes que la acción de una regla con prioridad 1. For examples of the way in which priority (or salience) can be used in normalization rules, see Alma Normalization Rule Examples.Note that priority (or salience) is only necessary when the fields in the rules are the same. Otherwise, when each rule deals with different fields, multiple rules are performed from top to bottom.
Learn how to create normalization rules that delete specified fields from records, or change the contents of these fields in the Normalization Routine Syntax for Deletion or Content Change video (9:57 mins).
<conditions on MARC record> contains one or more Boolean clauses that apply to the record. If <conditions on MARC record> returns TRUE, the rule is applied to the record; otherwise, the rule is not applied and the record is not processed.
- “When” must be the only word in the first line. La condición debe ubicarse en una línea separada.
- You can use multiple conditions on the whole record in the “When” condition only.
- Aunque se permite incluir varios operadores booleanos en las reglas, cuando son seleccionados un gran número de operadores booleanos, es probable que el rendimiento se ralentice. Por lo tanto, cada regla debe incluir como máximo 200 operadores booleanos.
- Si no se especifica, la condición funcionará a nivel de registro. Si desea que la condición funcione en cada campo MARC21 por separado, deberá especificar la condición por campo. Por ejemplo, cuando hay varios campos MARC21 con la misma etiqueta.
Comprender los caracteres de escape en las reglas de normalización
Al escribir reglas de normalización, es posible que necesite incluir caracteres especiales como comillas, tabulaciones o barras invertidas. Para hacerlo correctamente, se utilizan caracteres de escape, que son combinaciones especiales que indican al sistema cómo interpretar estos símbolos.
Secuencias de escape válidas
Alma reconoce las siguientes secuencias de escape:
- \b - retroceso
- \t - tab
- \n - nueva línea
- \f - salto de página
- \r - retorno de carro
- \" - comillas dobles
- \' - comilla simple
- \\ - barra invertida
Estas secuencias deben comenzar con una barra invertida seguida de un carácter válido.
Errores comunes que se deben evitar
El uso de un número incorrecto de barras invertidas puede provocar errores. Por ejemplo:
- \z o \\\z no son válidos y provocarán un error.
- Una barra invertida (\) sola sin un carácter de escape válido tampoco es válida.
Cómo corregir errores
Si aparece un error como:
"Secuencia de escape no válida (las válidas son \b \t \n \f \r "')"
Puedes solucionarlo ajustando las barras invertidas. Aquí hay algunos ejemplos:
- replacing \\\ with \\
- replacing \. with .
- replacing \( with ( and \) with )
- replacing \\\| with \\|
Estos cambios conservan el comportamiento previsto de la regla y evitan errores de sintaxis.
Elementos de registro
Las condiciones y acciones se aplican a los elementos del registro, como el registro MARC, los campos (uno o más), los indicadores, los subcampos (uno o más) y el contenido de campos/subcampos.
Para probar una condición o aplicar una acción a un elemento del registro, el elemento debe coincidir con la siguiente sintaxis:
| Expresión | Significado |
|---|---|
| "<tag>", "<new tag>" | Representa una etiqueta de campo, por ejemplo, 001, 245, etc. |
| "<oldCode>", "<newCode>" | Representa un código de subcampo, por ejemplo, a, b, c. |
| "<element>" for a data field | Los siguientes son valores posibles para el campo de datos:
|
| "<element>" for a control field | Los siguientes son valores posibles para un campo de control:
|
| "<element>" for a fixed position field |
The following are the possible values for a fixed position UNIMARC/CNMARC 1XX field:
Relevant only for UNIMARC/CNMARC 1XX fields. |
| CONDITION at record level | Las siguientes son opciones de condición posibles. See the next section (Conditions) for important information.
The following are the possible condition options relevant only for UNIMARC/CNMARC 1XX fields:
|
Conditions
Conditions can be defined at the entire rule level (WHEN), or at a specific action level (IF). La misma condición se comportará diferente según el nivel para el que esté definida.
- WHEN clause – A condition that must be met by the entire record in order to determine whether the rule is applied to the record
- IF(within an action) – A condition that applies to a single field in order to determine whether the specific action is taken on that field
Las condiciones pueden ser:
-
containsScript – Use this condition to detect a specific language. The containsScript condition uses the following fixed list of languages for which you can check: Arabic, Armenian, Bengali, Bopomofo, Braille, Buhid, Canadian_Aboriginal, Cherokee, Cyrillic, Devanagari, Ethiopic, Georgian, Greek, Gujarati, Gurmukhi, Han, Hangul, Hanunoo, Hebrew, Hiragana, Inherited, Kannada, Katakana, Khmer, Lao, Latin, Limbu, Malayalam, Mongolian, Myanmar, Ogham, Oriya, Runic, Sinhala, Syriac, Tagalog, Tagbanwa, TaiLe, Tamil, Telugu, Thaana, Thai, Tibetan, and Yi. Véase el ejemplo siguiente de sintaxis:rule "Is CJK in Authority" when containsScript "Han" "1**" then set indication."true" end
- exists <element> – At least one match is found
- exists <element> – Applies to data fields. Al utilizarla en una cláusula IF, tanto el elemento de la acción como el elemento evaluado por la condición deben ser el mismo campo (de datos).
- existsControl <element> – Applies to control fields. Al utilizarla en una cláusula IF, tanto el elemento de la acción como el elemento evaluado por la condición deben ser el mismo campo (de control).
- existsMoreThanOnce <element> – Multiple matches are found. Se aplica a campos de datos. Al utilizarla en una cláusula IF, tanto el elemento de la acción como el elemento evaluado por la condición deben ser el mismo campo (de datos).
- not exists <element> – No match is found
- not exists <element> – Applies to data fields. Al utilizarla en una cláusula IF, tanto el elemento de la acción como el elemento evaluado por la condición deben ser el mismo campo (de datos).
- not existsControl <element> – Applies to control fields. Al utilizarla en una cláusula IF, tanto el elemento de la acción como el elemento evaluado por la condición deben ser el mismo campo (de control).
-
recordHasDuplicateSubfields(for indication rules; see Working with Indication Rules) – Returns true if duplicate subfields (subfield and its contents) are found for the current record according to the fields, subfields, and the characters to ignore (charsToIgnore) string that were passed as parameters in the following format:recordHasDuplicateSubfields "<tag>" "<code>" "<charsToIgnore>"Se pueden especificar múltiples etiquetas (campos) separados por comas. Se pueden especificar múltiples códigos (subcampos) sin espacios para separarlos. One or more characters (alphanumeric or punctuation) with no spaces to separate them can be specified as characters to ignore at the end of the content in the subfields that are being evaluated for duplication. See Example 6 for more information.For the records that meet the recordHasDuplicateSubfields condition (returns true), a set of the records is created.
Each IF clause action can have one of the following formats:
- Applies if a specific condition is not true, for example:addControlField "{element}"if(not exists "{condition}")
- Applies if a specific condition is true, for example:addControlField "{element}"if(exists "{condition}")
- Applies unconditionally, for example:addControlField "{element}"
The Boolean OR operator can be used in a consequence statement by using the pipe (|) symbol, for example:removeField "866" if (not exists "866.8.0 | 99". If the pipe symbol is part of the value, use four backslashes (\\\\) to escape it, for example:removeField "866" if (exists "866.8.0 \\\\| 99")
The if (exists...) condition is met if the value in the condition appears somewhere in the record. No es posible copiar/eliminar un subcampo con un valor específico utilizando esta regla. Para eliminar o copiar un subcampo con un valor específico, utilice las reglas de transformación XSL.
List of Actions
La siguiente tabla ofrece una lista de acciones disponibles.
| Acción | Formato / Ejemplo | Comentario |
|---|---|---|
| Reemplazar campos y subcampos con otros campos y subcampos | changeControlField "<tag>" to "<new tag>"
Example:changeControlField "007" to "008"
|
Cambia el identificador de etiqueta de un campo controlado; no modifica los contenidos. |
| changeField "<tag>" to "<new tag>"
Example:changeField "245" to "246"
|
Cambia el identificador de etiqueta; no modifica los indicadores ni los subcampos. | |
| changeSubField "<tag>.<code>" to "<new code>"
changeSubFieldOnlyFirst "<tag>.<code>" to "<new code>"
changeSubFieldExceptFirst "<tag>.<code>" to "<new code>"
Example:changeSubField "035.b" to "a"
|
Changes the subfields (or only the first subfield, or all except the first subfield) "<code>" to the subfield "<new code>" in field "<tag>". | |
| changeFirstIndicator "<tag>" to "<value>"
changeSecondIndicator "<tag>" to "<value>"
Example:changeFirstIndicator "245" to "3"
|
Sets the value of the specified indicator in tag <tag>. | |
| combineFields "<tag>" excluding "<comma-separated subfield list>"
Example:combineFields "852" excluding "a,b"
|
Combinar todos los campos del número especificado. Copiar todos los subcampos de la segunda línea y las subsiguientes líneas a la primera línea, excluyendo los subcampos nombrados; solo las primeras ocurrencias de los subcampos excluidos son copiadas, y solo si no existen ya en la primera línea. | |
| Añadir campos y subcampos | addField "<tag>.<code>.<value>"
addField "<tag>.{<ind1>,<ind2>}.<code>. <value>"
Example:addField "999.a.RESTRICTED"
|
Añadir el campo al registro MARC. Establecer el valor indicado como el valor del subcampo. |
| addControlField "<tag>.<value>"
Example:addControlField "008.820305s1991####nyu###########001#0#eng##"
|
Añade el campo controlado al registro MARC. | |
| addSubField "<tag>.<code>.<value>"
addSubField "<tag>.{<ind1>,<ind2>}.<code>.<value>"
Example:addSubField "245.h.[Journal]"
|
Adds the subfield <code> with value <value> to field <tag>. Si el campo no existe, no se hace nada. | |
| addSystemNumber "<element>" from "<tag>" prefixed by "<prefix tag>"
Example:addSystemNumber "035.a" from "001" prefixed by "003"
|
Makes the data field <element> equal to the contents of the second control field <prefix tag> in parentheses followed by the contents of the first control field <tag>.
For example, if 001 has the value 9945110100121 and 003 has the value DAV, the example condition on the left will produce 035 with the value ‡(DAV)9945110100121.
|
|
| Copia campos | copyField "<tag>" to "<new tag>"
copyField "<tag>.<code>" to "<new tag>.<new code>"
copyField "<tag>" to "<new tag>.{<ind1>,<ind2>}"
Example:copyField "971.a" to "100.u"
|
Copia el campo a otro campo. In the first version, the subfields are not specified (<code> and <new code>), and the new field contains all the same subfields as the old field. In the second version, if just <new code> is not specified, the new subfield is the same as the one specified by <code>.
copyField creates a separate field rather than adding it to any existing field. You may want to combine the new field with any existing fields (see combineFields). |
| Elimina campos y subcampos | removeControlField "<tag>"
Example:removeControlField "009"
|
Elimina todas las ocurrencias del campo controlado.
Tenga en cuenta que si elimina el campo de control 008, Alma vuelve a crearlo inmediatamente si usted no lo hace. Considere volver a añadir el campo después de eliminarlo, por ejemplo: rule "remove 008" when (TRUE) then removeControlField "008" addControlField "008.######s2013####xx######r#####000#0#eng#d" end |
| removeField"<tag>"
Example:removeField "880"
|
Removes all occurrences of the field <tag>. | |
| removeSubField "<tag>.<code>"
Example:removeSubField "245.h"
|
Removes all occurrences of the subfield <code> from the indicated field. | |
| Substituye texto en campos o subcampos | replaceControlContents "<tag>.{<position>,<length>}. <value>" with "<new value>"
Example:replaceControlContents"LDR.{7,1}.s" with "m"
|
Replaces <value> with "<new value>" in starting position <position> to <position>+<length> of control field <tag>. Replaces only the text that matches <value>. |
| replaceContents "<tag>.<code>.<value>" with "<new value>"
replaceContentsOnlyFirst "<tag>.<code>.<value>" with "<new value>"
replaceContentsExceptFirst "<tag>.<code>.<value>" with "<new value>"
Example:replaceContents"245.h.[Journal]" with "[Book]"
|
Replaces the matching strings (or every instance of the matching string in the first matching subfield, or all matching strings in all matching subfields except the first matching subfield) <value> in the subfield <code> of field "<tag>" with "<new value>". The string or part of the string that does not match <value> is not modified. | |
| replaceSubFieldContents "<tag>.<code>" with "<tag>.<code>"
Example:replaceSubFieldContents "245.b" with "100.a"
|
Substituye los contenidos del subcampo por contenidos de otro subcampo. | |
|
replaceFixedContents "<tag>.{<1_ind>,<2_ind>}.<code>.{<position>,<length>}.<value>" with "<new value>" Example:replaceFixedContents "100.{1,2}.a.{0,8}.20150226" with "20220724" |
Replaces <value> with <new value> in UNIMARC and CNMARC 1XX fixed position fields. Relevant only for UNIMARC/CNMARC 1XX fields. |
|
| Añade texto en subcampos | prefix "<tag>.<code>" with "<value>"
Example:prefix "035.b" with "(OCoLC)"
|
Adds a prefix to the value of subfield "<code>" in the field "<tag>".
The new value will be <value> followed by the old value. |
| prefixSubField "<tag>.<code>" with "<source tag>.<source code>"
Example:prefixSubField "910.a" with "906.a"
|
Adds the value of the subfield "<source code>" in the field "<source tag>" as a prefix to the subfield "<code>" in the field "<tag>".
The new value will be the value of the subfield "<source code>" in the field "<source tag>" followed by the old value. |
|
| suffix "<tag>.<code>" with "<value>"
Example:suffix "035.b" with "(OCoLC)"
|
Adds a suffix to the value of subfield "<code>" in the field "<tag>".
The new value will be the old value followed by <value>. |
|
| suffixSubField "<tag>.<code>" with "<source tag>.<source code>"
Example:suffixSubField "910.a" with "907.c"
|
Adds the value of the subfield "<source code>" in the field "<source tag>" as a suffix to the subfield "<code>" in the field "<tag>".
The new value will be the old value followed by the value of the subfield "<source code>" in the field "<source tag>". |
|
| Mantener información de agencia en registros bibliográficos y de autoridad
Por ejemplo, esta sintaxis puede usarse en reglas de normalización que estén seleccionadas en la Lista de tareas de configuración de metadatos bibliográficos MARC 21 para normalizar los registros bibliográficos de la Zona de red al guardar. Esta función está en construcción. Para activar esta sintaxis, contactar al soporte de Ex Libris. |
addCreatingAgency "<tag>.<code>"
Example:addCreatingAgency "040.a"
|
Adds the creating agency ISIL code to the subfield in "<code>" in the field "<tag>". |
| addModifyingAgency "<tag>.<code>"
Example:addModifyingAgency "040.d"
|
Adds the modifying agency ISIL code to the subfield in "<code>" in the field "<tag>". If there already is a modifying agency in the "<tag>.<code>", this adds another agency ISIL code. | |
| replaceModifyingAgency "<tag>.<code>"
Example:replaceModifyingAgency "040.d"
|
Adds the modifying agency ISIL code to the subfield in "<code>" in the field "<tag>". If any modifying agencies already exist in the "<tag>.<code>", all of them are replaced. | |
| Dividir subcampos | splitSubField "<tag>.{ind1,ind2}.<code>.<delimiter>" to "<tag>.{<ind1>,<ind2>}.<code>" addSeq "<code>"
Example 1:splitSubField "866.a.;" to "555.{0,0}.a" addSeq "8"
Example 2:splitSubField "555.a. – " to "859.{0,0}.a" addSeq "8"
Example 3:splitSubField "859.a.\\\\."
Example 4:splitSubField "999.a.;" to "555.a" addSeq "8"
|
La etiqueta es obligatoria.
Los indicadores son opcionales. Dado que la división se produce en el nivel del subcampo, el código es obligatorio. El delimitador puede ser cualquier cadena. Si el delimitador no existe, el subcampo completo se copia como la primera (y única) ocurrencia, y la secuencia es añadida. The to component is optional. If it is specified, multiple occurrences of the to tag.code are created, each with the data until the delimiter. Ver los ejemplos 1 y 2. If the to component is not specified, the subfield is split to the additional same subfields in the same field as shown in example 3. The addSeq component is optional. It is not relevant if the to component is not specified. Cuando se especifica addSeq, el subcampo con una secuencia será añadido como en el ejemplo 1; y si el subcampo ya existe en el campo original, una secuencia (precedida de un punto) se añadirá a ese campo, como en el ejemplo 2. |
|
Eliminar subcampos duplicados |
correctDuplicateSubfields "<tag>" "<code>" Example: Removes duplicate subfields x, y and z from fields 610 and 630. rule "Remove duplicates" priority 1 when (TRUE) then correctDuplicateSubfields "610,630" "xyz" end |
Corrects duplicate subfields (for instance, subfields with the same code AND the same value) by keeping the first occurrence and removing the others from the current record according to the fields and subfields that were passed as parameters. You may want to use recordHasDuplicateSubfields to create the set that you supply to your normalization rule that uses correctDuplicateSubfields. See Example 6 for more information. For deduplication of subfields with different values, see:How to remove all but one of several similar subfields in the same field in MD Editor. |
|
Mover subcampos |
moveSubfieldsToEndOfField "<tag>" "<code>" Example: Moves subfields 9 and 2 to the end of field 650. rule "Move subfields to end of field" priority 1 when (TRUE) then moveSubfieldsToEndOfField "650" "92" end |
Mueve la primera ocurrencia de cada subcampo al final del campo y elimina las demás ocurrencias del mismo subcampo. Si se especifica más de un subcampo, estos se colocan al final en la misma secuencia, según se indique en la regla. En este ejemplo, el subcampo 9 se coloca al final seguido del subcampo 2. Note that the if statement is not supported with the moveSubfieldsToEndOfField action. |
|
Corregir campos duplicados del registro actual |
correctDuplicateFields "{fields}" Ejemplo: correctDuplicateFields "610,630,650" |
Esta acción toma un parámetro, campos, que contiene valores de campos separados por coma como 610,630,650. Esta acción corrige campos duplicados del registro actual de acuerdo a los campos que se aprobaron como parámetros. Esta acción solo puede utilizarse para identificar y corregir datos duplicados encontrados entre varias instancias del mismo campo. |
|
Buscar campos duplicados (Indication Rules; see Working with Indication Rules) |
recordHasDuplicateFields "{fields}" Example: correctDuplicateFields "610,630,650" |
Esta acción toma un parámetro, campos, que contiene valores de campos separados por coma como 610,630,650. Esta acción puede ser verdadera o falsa. El resultado es verdadero si se encuentran campos duplicados en el registro actual de acuerdo a los campos que se aprobaron como parámetro. Esta acción solo puede utilizarse para identificar y corregir datos duplicados encontrados entre varias instancias del mismo campo. |
Comodines y caracteres especiales
While the use of regular expressions in Alma Normalization Rules is not currently fully supported, some regular expressions can be used – for examples of these, see Alma Normalization Rule Examples.
The subfield separator ($$) cannot appear anywhere in the rule, including the rule name.
A hash character (#) at the beginning of a line indicates that the rest of the line is a comment, and is ignored when processing the rule.
The hash character (#) is not treated as a space by the normalization rules function replaceControlContents. The hash (#) is not a wild card and is not supported by this function.
The asterisk (*) is used to match any string, including a string of zero length. For example,"<tag>.<*>.<value>" applies to all the subfields in the tag <tag> that have the value <value>.* is "greedy", so it matches as many characters as possible in the string. For example: if you have a string "a b c b d b e", the pattern "b*b" matches "b c b d b", not just "b c b".
Empty indicators (but not fields or subfields) are indicated by a hyphen (-). For example,"<tag> {-,<ind2>}" returns all the fields where the MARC tag is <tag>, the first indicator is not defined, and the second indicator is <ind2>.
Si el texto de un subcampo contiene un punto como último carácter, utilice cuatro barras invertidas para establecer una coincidencia con el punto. Por ejemplo:
Las comillas dobles (solo) pueden usarse en las condiciones. Para usar comillas dobles como parte de una condición, utilizar comillas simples para encerrar el texto de la regla (') en lugar de comillas dobles ("). This way you can use double quotation marks inside the text following a double backslash (\\).
Las fechas en hebreo (solo) pueden usarse en las condiciones. (El hebreo se lee de derecha a izquierda, de modo que las dos barras invertidas en el siguiente ejemplo en realidad están antes de las comillas dobles.)
- No pueden usarse comodines como primer carácter de una condición o un valor.
- To use a literal backslash (\), escape it with another backslash:\\.
- Use four backslashes (\\\\) to escape a period when it is the last character in the string. When the period is immediately followed by another character, it does not require four backslashes (as in addField "907.a.F.L.T\\\\."). Sin embargo, es una práctica recomendada utilizar siempre cuatro barras invertidas en la regla de normalización para asegurarse de que los resultados deseados sean consistentes. Véase los siguientes ejemplos:
- Como se indicó más arriba, si se utiliza una comilla doble (solo) en una condición que es escapada usando comillas simples, o una comilla simple que es escapada usando comillas simples, se debe usar, a su vez, dos barras invertidas para escapar la comilla doble o simple.
- If the pipe symbol is part of the condition, use four backslashes to escape it, for example:removeField "866" if (exists "866.8.0\\\\|99"). Esto solo es necesario cuando se usa la pleca en la condición.
Ejemplo: uso del punto en una regla de normalización con replaceContents
Ejemplo de registro con puntos:
245 00 $$a Feminist literary theory. : $$b a reader / $$c edited by Mary Eagleton.
246 0# $$a F.L.T.
Regla de normalización para el ejemplo anterior:
Ver la figura a continuación para ejemplos del antes y el después.
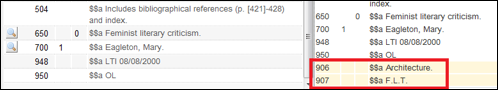
Ejemplo: uso del punto en una regla de normalización con addField
A continuación hay un ejemplo de un registro al que deben añadírsele puntos:
906 $$a Architecture.
907 $$a F.L.T.
A continuación se halla la regla de normalización para el ejemplo anterior, en la que se emplea la práctica recomendada de incluir siempre barras invertidas:
Véase la figura a continuación para ejemplos del registro antes y después.
Ejemplos de reglas de normalización
For a list of over 100 normalization rule examples and other normalization rule documents, see Alma Normalization Rule Examples.
For more information on creating normalization rules for bibliographic records in XSL format, see Alma XSL Normalization Rule Examples.
Alma es compatible con la versión 3.0 de XSL.
Page tags: article:topicproduct:almacontent:Documentationlang:englishactionsRulesyntaxnormalization rule syntaxconditionselements
