
Utilizzo delle regole di normalizzazione
Panoramica e istruzioni per lavorare con le Regole di normalizzazione.
- Amministratore catalogo
- Gestore catalogo
- Catalogatore
Normalization rules are used to change or update bibliographic metadata at various stages, for example when the record is saved in the Metadata Editor, imported using the import profile, imported from external search resource, or edited using the "Enhance the record" menu in the Metadata Editor. Le Regole di normalizzazione sono scritte in una sintassi specifica, consentendo di creare regole per apportare modifiche specifiche ai record. Ad esempio, è possibile modificare o eliminare il campo, e lo si può fare anche in modo condizionale, in base a una condizione che si verifica nel record bibliografico.
Normalization rules can be applied to individual records in the MD Editor or to a group of records:
- To apply normalization rules to an individual record, use the Enhance Record option (refer to the section MD Editor Menu and Toolbar Options) or Apply Changes to an individual record when you preview normalization rules (see To preview the outcome of a rule).
- To apply normalization rules to a set of records, you need to create a process using the MarcDroolNormalization, MarcXSLNormalization or DcDroolNormalization tasks (see Working with Normalization Processes) and specify the normalization rule created with the MD Editor (refer to the procedure To create a new normalization rule file). Once you have created the process, you can run a job using that process (see Running Manual Jobs on Defined Sets). In addition, you can create a process that enables application of normalization rules when selecting Save in the MD Editor (see Working with Normalization Processes).
Normalization rules are created by following a specific programming syntax and using the editing window provided in the MD Editor under the Rules tab.

Oltre a creare il Suo programma Regole di normalizzazione, può anche copiare/incollare le regole esistenti nella finestra di modifica o utilizzare esempi predefiniti (Regole tab) per sviluppare le Sue Regole di normalizzazione. See Normalization Rules Syntax for more information regarding the syntax for normalization rules and examples that you can copy to the editing window.
Utilizzando la funzionalità di anteprima nell'Editor MD, è possibile:
- Visualizza le Regole di normalizzazione e il record dei metadati affiancati
- Visualizzi in anteprima il risultato di una regola quando viene eseguita su un record di metadati
- Alternare tra la regola e l'anteprima delle modifiche
- Modifichi le regole e le testi immediatamente
- For a short overview of Normalization Rules, watch Normalization Rules(6:00).
- For detailed information on Normalization rules with examples, watch Normalization Rules(1 hr).
Creazione delle regole di normalizzazione
This section describes how to create a normalization rule or copy a rule from the Community Zone, work with previously created rules, and preview the rule's outcome when it is run on a single metadata record. For more information, see the Normalization Rules area on this page.
Note that normalization rules on Institution Zone records that are linked to Network Zone records can be applied only to local fields. To apply normalization rules to such records, run the normalization rules and normalization processes only in the Network institution.
For Network Zone consortia members, users can control whether to save new rules locally or in a network institution. To make this selection, open the Records or Templates area and navigate to New > Placement Options. Si noti che questa selezione è per l'utente.
- On the MD Editor page (Resources > Cataloging > Open Metadata Editor), open the Rules area.
- To create a normalization rule for a MARC or Dublin Core record, select New > Normalization. La finestra di dialogo Regole di normalizzazione Properties (Nuova regola) si apre.
 Finestra di dialogo Proprietà delle regole di normalizzazione
- Enter a name and a description for the normalization rule.
- The word rule must not be capitalized if used in the rule name. If capitalized, the rule does not work.
- Non usi una barra rovesciata (\) nel nome della regola! Otherwise, the rule cannot be used for the filter set functionality.
- Il limite di caratteri per i nomi e le descrizioni delle regole è di 255 caratteri.
- To create a normalization rule for a MARC record, select Drool. To create a normalization rule for a DC (Dublin Core) record, select XSL.
MARC record normalization rules also support XSL.
- Select an access option,Private or Shared. Se seleziona Privato, solo Lei potrà lavorare sulla regola e la regola non potrà essere inclusa in un processo di normalizzazione. Se seleziona Condiviso, la Sua regola verrà condivisa tra i catalogatori. In this case, more than one user can view the rule at the same time; if two or more people have the rule open for editing, a warning message appears when one of you tries to save changes. (Ha la possibilità di mantenere le Sue modifiche o di consentire all'altro Utente di apportare e salvare le modifiche.)
- Select Save.The Metadata Editor editing pane opens. You can include existing rule syntax (Edit > Add Rule > {type of rule}) or define a rule (for details, see Normalization Rules Syntax).
- Seleziona Salva. La regola viene aggiunta alla Lista dei file di regole sotto la Regole di normalizzazione tab.
- On the Metadata Editor page (Resources > Cataloging > Open Metadata Editor), select the Rules tab and expand the Normalization folder.
- Per copiare, apri la cartella Community , fai clic con il pulsante destro del mouse sulla regola che desidera copiare e selezioni Duplica. Si apre la finestra di dialogo Regola duplicato. Inserisca il Suo nome e la descrizione e indichi se desidera salvare la regola come privata (disponibile solo per Lei) o condivisa (disponibile per tutti gli Utenti della Sua istituzione). The dialog box indicates the Alma user name and contact email of the user who contributed the rule to the Community Zone. Se ha domande, può contattare questo Utente.
- Per contribuire con la Sua regola alla Community Zone, faccia clic con il pulsante destro del mouse sulla regola e selezioni Contribuisci a CZ. The Rule Sharing dialog opens. Provide a descriptive name and description, and select Save to save the rule in the Community Zone.
- On the Metadata Editor page (Resources > Cataloging > Open Metadata Editor), select the Rules tab and expand the Normalization folder to display the saved rules.
- Selezioni la regola con cui desidera lavorare e scelga una delle seguenti opzioni:
- Edit – Opens the text box with the rule(s) syntax, enabling you to modify this syntax (for details, see Normalization Rules Syntax).
- Delete – Select Yes to confirm the rule file's deletion.
- Duplica – Duplica il file di regole selezionato, consentendo di modificarlo e salvarlo come nuova regola senza influire sul file originale.
- Proprietà – Apre la finestra di dialogo delle Proprietà delle Regole di normalizzazione, consentendo di modificare le proprietà del file di regole.
- To rename the rule, duplicate the rule, give the duplicate the desired name, and then delete the old rule.
- Locate the bibliographic record with which you want to work (using the Repository Search or within the MD Editor > Records tab) and open it in the Metadata Editor.
- PressF6 or select the Split Editor icon.
- Select the Rules tab in the left pane and expand the Normalization folder.
- Right-select the rule that you want to preview or test in the Private or Shared(not the Community) folder and select Edit.
 The rule is displayed in the Metadata Editor right pane.

- Selezionare Anteprima. The rule is applied to the record, and the outcome appears.
To update Network records, the normalization must be run by the Network institution (not by a member). An institution cannot update Network records; therefore, the normalization is only applied to local fields (the local extensions of the member). When previewing a rule for a Network record, the following message is displayed:Note that the rules are applied only to local fields when the normalization process is run.
- Select Apply Changes to save the modifications to the record or select Back to normalization rules to continue editing.
- When you have made your final changes to the normalization rule, select Save and test using external record to save the final version of your normalization rule.For details, see Testing Normalization Rules for External Data Sources.
Normalization Rules for Dublin Core and MODS Records
Nell'editor dei metadati, sono presenti i seguenti tipi di regole relativi a Dublin Core e MODS:
- Regole di indicazione XSL
- XSL Regole di normalizzazione
XSL Normalization Rule does not support discovery:local.
Dublin Core and MODS normalization rules cannot be written in a regular Normalization Rule format, but only as an XSL. This means that you compose the XSL directly in the Metadata Editor (as explained above), or you can compose it in Notepad (or another external application of your choice) and then copy it to the Metadata Editor.
You can view the below examples of XSL Normalization Rules for Dublin Core in the Community Zone in the Metadata Editor:
- EXL – Cambiare il valore dc:language da en a inglese
- EXL – Regola generica per sostituire una stringa nel record di Dublin Core
- EXL_Add_field_accessRights
- Scriva l'XSL in un'applicazione esterna a Sua scelta.
- Open the Metadata Editor > Rules section.
- Copy and paste the XSL to the Metadata Editor and save the rule.
Regole di normalizzazione per Primo VE ed Esploro
In addition to Alma normalization rules, you can create normalization rules for Primo VE and Esploro. To create these rules, select New, and then select:
-
Normalization (Discovery) – This option appears only when Primo VE is defined in the system. Select this option if you are creating DC or XML normalization rules for bibliographic records that are loaded into Primo VE and not managed in Alma. For information regarding the syntax of these rules, see Normalization Rule Syntax for DC and XML Formats.
-
Normalization (Research) – This option appears only when Esploro is defined in the system. For details, see Managing Asset Normalization Rules(Esploro).
Normalization Rule Syntax
Rules can contain one or several other rules. Each rule contains a condition, and one or more actions to be applied to records. Le azioni vengono eseguite nell'ordine in cui appaiono all'interno della regola. Each action can be performed on a single field within a record. Actions are performed in the order in which they appear within the rule.
Le azioni stabilite nella regola con la priorità più alta vengono eseguite per prime. Actions stipulated in the rule with the higher priority are performed first. For example, the action in a rule with priority 2 is performed before the action in a rule with priority 1. For examples of the way in which priority (or salience) can be used in normalization rules, see Alma Normalization Rule Examples.Note that priority (or salience) is only necessary when the fields in the rules are the same. Otherwise, when each rule deals with different fields, multiple rules are performed from top to bottom.
Learn how to create normalization rules that delete specified fields from records, or change the contents of these fields in the Normalization Routine Syntax for Deletion or Content Change video (9:57 mins).
<conditions on MARC record> contains one or more Boolean clauses that apply to the record. If <conditions on MARC record> returns TRUE, the rule is applied to the record; otherwise, the rule is not applied and the record is not processed.
- “When” must be the only word in the first line. La condizione deve essere posta su una riga separata.
- You can use multiple conditions on the whole record in the “When” condition only.
- Sebbene sia consentito includere più operatori booleani nelle regole, quando ne viene selezionato un numero elevato, è probabile che le prestazioni risultino più lente. Thus each rule should include no more than 200 Boolean operators.
- If not specified, the condition will work on the record level. If you want the condition to work on each MARC21 field separately, the condition should be specified per field. For example, when there are multiple MARC21 fields with the same tag.
Comprendere i caratteri di escape nelle regole di normalizzazione
Quando si scrivono Regole di normalizzazione, potrebbe essere necessario includere caratteri speciali come virgolette, tabulazioni o barre rovesciate. Per farlo correttamente, si usano i caratteri di escape, che sono combinazioni speciali che indicano al sistema come interpretare questi simboli.
Sequenze di escape valide
Alma riconosce le seguenti sequenze di escape:
- - tasto di cancellazione
- - tab
- - nuova linea
- - feed modulo
- - ritorno a capo
- \" - virgolette doppie
- \' - apostrofo singolo
- \ - barra rovesciata
Queste sequenze devono iniziare con una barra rovesciata singola seguita da un carattere valido.
Errori comuni da evitare
L'utilizzo di un numero errato di backslash può causare errori. Ad esempio:
- \z o \\\z non sono validi e genereranno un errore.
- Anche una barra rovesciata (\) isolata senza un carattere di escape valido è anch'essa non valida.
Come correggere gli errori
Se vede un errore come:
«Sequenza di escape non valida (quelle valide sono \b \t \n \f \r)»
È possibile risolverlo adeguando le barre rovesciate. Ecco alcuni esempi:
- replacing \\\ with \\
- replacing \. with .
- replacing \( with ( and \) with )
- replacing \\\| with \\|
These changes preserve the intended behaviour of your rule while avoiding syntax errors.
Record Elements
Condizioni e azioni si applicano agli elementi record, come il Record in formato MARC, campo (uno o più), Indicatore (di campo), Sottocampo (uno o più) e contenuti di campo/Sottocampo.
Per testare una condizione o applicare un'azione a un elemento del record, l'elemento deve corrispondere alla seguente sintassi:
| Espressione | Senso |
|---|---|
| "<tag>", "<new tag>" | Rappresenta un tag di campo, ad esempio 001, 245, ecc. |
| "<oldCode>", "<newCode>" | Rappresenta un codice sottocampo, ad esempio a, b, c. |
| "<element>" for a data field | Di seguito sono elencati i possibili valori per il campo dati:
|
| "<element>" for a control field | I seguenti sono i possibili valori per un campo di controllo:
|
| "<element>" for a fixed position field |
The following are the possible values for a fixed position UNIMARC/CNMARC 1XX field:
Relevant only for UNIMARC/CNMARC 1XX fields. |
| CONDIZIONE a livello di record | Di seguito sono riportate le possibili opzioni di condizione. See the next section (Conditions) for important information.
The following are the possible condition options relevant only for UNIMARC/CNMARC 1XX fields:
|
Condizioni
Le condizioni possono essere definite a livello di regola completa (WHEN) o a livello di azione specifica (IF). La stessa condizione si comporterà in modo diverso a seconda del livello al quale è definita.
- Clausola WHEN – Una condizione che deve essere soddisfatta dall'intero record in Ordine per determinare se la regola viene applicata al record
- IF(within an action) – A condition that applies to a single field in order to determine whether the specific action is taken on that field
Le condizioni possono essere:
-
containsScript – Use this condition to detect a specific language. The containsScript condition uses the following fixed list of languages for which you can check: Arabic, Armenian, Bengali, Bopomofo, Braille, Buhid, Canadian_Aboriginal, Cherokee, Cyrillic, Devanagari, Ethiopic, Georgian, Greek, Gujarati, Gurmukhi, Han, Hangul, Hanunoo, Hebrew, Hiragana, Inherited, Kannada, Katakana, Khmer, Lao, Latin, Limbu, Malayalam, Mongolian, Myanmar, Ogham, Oriya, Runic, Sinhala, Syriac, Tagalog, Tagbanwa, TaiLe, Tamil, Telugu, Thaana, Thai, Tibetan, and Yi. Veda il seguente esempio di sintassi:rule "Is CJK in Authority" when containsScript "Han" "1**" then set indication."true" end
- exists <element> – At least one match is found
- exists <element> – Applies to data fields. Quando utilizzato in una clausola IF, sia l'elemento di azione che l'elemento testato dalla condizione devono essere lo stesso campo (dati).
- existsControl <element> – Applies to control fields. Quando utilizzato in una clausola IF, sia l'elemento di azione che l'elemento testato dalla condizione devono essere lo stesso campo (di controllo).
- existsMoreThanOnce <element> – Multiple matches are found. Si applica al campo dati. Quando utilizzato in una clausola IF, sia l'elemento di azione che l'elemento testato dalla condizione devono essere lo stesso campo (dati).
- not exists <element> – No match is found
- not exists <element> – Applies to data fields. Quando utilizzato in una clausola IF, sia l'elemento di azione che l'elemento testato dalla condizione devono essere lo stesso campo (dati).
- not existsControl <element> – Applies to control fields. Quando utilizzato in una clausola IF, sia l'elemento di azione che l'elemento testato dalla condizione devono essere lo stesso campo (di controllo).
-
recordHasDuplicateSubfields(for indication rules; see Working with Indication Rules) – Returns true if duplicate subfields (subfield and its contents) are found for the current record according to the fields, subfields, and the characters to ignore (charsToIgnore) string that were passed as parameters in the following format:recordHasDuplicateSubfields "<tag>" "<code>" "<charsToIgnore>"È possibile specificare più tag (campo) separati da virgole. È possibile specificare più codici (Sottocampo) senza spazi per separarli. One or more characters (alphanumeric or punctuation) with no spaces to separate them can be specified as characters to ignore at the end of the content in the subfields that are being evaluated for duplication. See Example 6 for more information.For the records that meet the recordHasDuplicateSubfields condition (returns true), a set of the records is created.
Ogni azione della clausola IF può avere uno dei seguenti Formato:
- Applies if a specific condition is not true, for example:addControlField "{element}"if(not exists "{condition}")
- Applies if a specific condition is true, for example:addControlField "{element}"if(exists "{condition}")
- Applies unconditionally, for example:addControlField "{element}"
The Boolean OR operator can be used in a consequence statement by using the pipe (|) symbol, for example:removeField "866" if (not exists "866.8.0 | 99". If the pipe symbol is part of the value, use four backslashes (\\\\) to escape it, for example:removeField "866" if (exists "866.8.0 \\\\| 99")
The if (exists...) condition is met if the value in the condition appears somewhere in the record. Non è possibile copiare o rimuovere un sottocampo con un valore specifico utilizzando questa regola. Per rimuovere o copiare un sottocampo con un valore specifico, utilizzi le regole di trasformazione XSL.
Elenco delle Azioni
The following table provides a list of available actions.
| Azione | Formato/Esempio | Commento |
|---|---|---|
| Sostituisca campo e Sottocampo con altri campo e Sottocampo | changeControlField "<tag>" to "<new tag>"
Example:changeControlField "007" to "008"
|
Cambia il tag identificativo di un campo di controllo; non modifica il contenuto. |
| changeField "<tag>" to "<new tag>"
Example:changeField "245" to "246"
|
Modifica il tag identificativo; non modifica Indicatore (di campo) né Sottocampo. | |
| changeSubField "<tag>.<code>" to "<new code>"
changeSubFieldOnlyFirst "<tag>.<code>" to "<new code>"
changeSubFieldExceptFirst "<tag>.<code>" to "<new code>"
Example:changeSubField "035.b" to "a"
|
Changes the subfields (or only the first subfield, or all except the first subfield) "<code>" to the subfield "<new code>" in field "<tag>". | |
| changeFirstIndicator "<tag>" to "<value>"
changeSecondIndicator "<tag>" to "<value>"
Example:changeFirstIndicator "245" to "3"
|
Sets the value of the specified indicator in tag <tag>. | |
| combineFields "<tag>" excluding "<comma-separated subfield list>"
Example:combineFields "852" excluding "a,b"
|
Combina tutti i campi del numero specificato. Copia tutti i Sottocampo dalla seconda e dalle successive righe alla prima riga, escluso il Sottocampo nominato; solo le prime occorrenze del Sottocampo escluso vengono copiate, e solo se non esistono già nella prima riga. | |
| Aggiungi campo e sottocampo | addField "<tag>.<code>.<value>"
addField "<tag>.{<ind1>,<ind2>}.<code>. <value>"
Example:addField "999.a.RESTRICTED"
|
Aggiunge il campo al record in formato MARC. Impostare il valore del sottocampo al valore indicato. |
| addControlField "<tag>.<value>"
Example:addControlField "008.820305s1991####nyu###########001#0#eng##"
|
Aggiunge il campo di controllo al record in formato MARC. | |
| addSubField "<tag>.<code>.<value>"
addSubField "<tag>.{<ind1>,<ind2>}.<code>.<value>"
Example:addSubField "245.h.[Journal]"
|
Adds the subfield <code> with value <value> to field <tag>. Se il campo non esiste, non viene eseguita alcuna azione. | |
| addSystemNumber "<element>" from "<tag>" prefixed by "<prefix tag>"
Example:addSystemNumber "035.a" from "001" prefixed by "003"
|
Makes the data field <element> equal to the contents of the second control field <prefix tag> in parentheses followed by the contents of the first control field <tag>.
Ad esempio, se 001 ha il valore 9945110100121 e 003 ha il valore DAV, la condizione di esempio a sinistra produrrà 035 con il valore ‡(DAV)9945110100121.
|
|
| Copia il campo | copyField "<tag>" to "<new tag>"
copyField "<tag>.<code>" to "<new tag>.<new code>"
copyField "<tag>" to "<new tag>.{<ind1>,<ind2>}"
Example:copyField "971.a" to "100.u"
|
Copia il campo in un altro campo. In the first version, the subfields are not specified (<code> and <new code>), and the new field contains all the same subfields as the old field. In the second version, if just <new code> is not specified, the new subfield is the same as the one specified by <code>.
copyField crea un campo separato anziché aggiungerlo a un campo esistente. Potrebbe voler combinare il nuovo campo con un campo esistente (vedi combineFields). |
| Elimina campo e sottocampo | removeControlField "<tag>"
Example:removeControlField "009"
|
Rimuove tutte le occorrenze del campo di controllo.
Nota che se rimuove il campo di controllo 008, Alma lo ricrea immediatamente se non lo fa. Si consideri di riaggiungere il campo dopo averlo rimosso, per esempio: rule "remove 008" when (TRUE) then removeControlField "008" addControlField "008.######s2013####xx######r#####000#0#eng#d" end |
| removeField"<tag>"
Example:removeField "880"
|
Removes all occurrences of the field <tag>. | |
| removeSubField "<tag>.<code>"
Example:removeSubField "245.h"
|
Removes all occurrences of the subfield <code> from the indicated field. | |
| Sostituisci il testo nel campo o nel sottocampo | replaceControlContents "<tag>.{<position>,<length>}. <value>" with "<new value>"
Example:replaceControlContents"LDR.{7,1}.s" with "m"
|
Replaces <value> with "<new value>" in starting position <position> to <position>+<length> of control field <tag>. Replaces only the text that matches <value>. |
| replaceContents "<tag>.<code>.<value>" with "<new value>"
replaceContentsOnlyFirst "<tag>.<code>.<value>" with "<new value>"
replaceContentsExceptFirst "<tag>.<code>.<value>" with "<new value>"
Example:replaceContents"245.h.[Journal]" with "[Book]"
|
Replaces the matching strings (or every instance of the matching string in the first matching subfield, or all matching strings in all matching subfields except the first matching subfield) <value> in the subfield <code> of field "<tag>" with "<new value>". The string or part of the string that does not match <value> is not modified. | |
| replaceSubFieldContents "<tag>.<code>" with "<tag>.<code>"
Example:replaceSubFieldContents "245.b" with "100.a"
|
Sostituisce il contenuto del sottocampo con il contenuto di un altro sottocampo. | |
|
replaceFixedContents "<tag>.{<1_ind>,<2_ind>}.<code>.{<position>,<length>}.<value>" with "<new value>" Example:replaceFixedContents "100.{1,2}.a.{0,8}.20150226" with "20220724" |
Replaces <value> with <new value> in UNIMARC and CNMARC 1XX fixed position fields. Relevant only for UNIMARC/CNMARC 1XX fields. |
|
| Aggiungi testo nel sottocampo | prefix "<tag>.<code>" with "<value>"
Example:prefix "035.b" with "(OCoLC)"
|
Adds a prefix to the value of subfield "<code>" in the field "<tag>".
The new value will be <value> followed by the old value. |
| prefixSubField "<tag>.<code>" with "<source tag>.<source code>"
Example:prefixSubField "910.a" with "906.a"
|
Adds the value of the subfield "<source code>" in the field "<source tag>" as a prefix to the subfield "<code>" in the field "<tag>".
The new value will be the value of the subfield "<source code>" in the field "<source tag>" followed by the old value. |
|
| suffix "<tag>.<code>" with "<value>"
Example:suffix "035.b" with "(OCoLC)"
|
Adds a suffix to the value of subfield "<code>" in the field "<tag>".
The new value will be the old value followed by <value>. |
|
| suffixSubField "<tag>.<code>" with "<source tag>.<source code>"
Example:suffixSubField "910.a" with "907.c"
|
Adds the value of the subfield "<source code>" in the field "<source tag>" as a suffix to the subfield "<code>" in the field "<tag>".
The new value will be the old value followed by the value of the subfield "<source code>" in the field "<source tag>". |
|
| Mantenere le informazioni dell'agenzia nei record bibliografici e di autorità
Ad esempio, questa sintassi può essere utilizzata nelle Regole di normalizzazione selezionate nella lista delle attività di configurazione dei metadati bibliografici MARC 21 per normalizzare il record bibliografico della Network Zone al momento del salvataggio. Questa funzionalità è in fase di sviluppo. Per abilitare questa sintassi, contatti l'assistenza di Ex Libris. |
addCreatingAgency "<tag>.<code>"
Example:addCreatingAgency "040.a"
|
Adds the creating agency ISIL code to the subfield in "<code>" in the field "<tag>". |
| addModifyingAgency "<tag>.<code>"
Example:addModifyingAgency "040.d"
|
Adds the modifying agency ISIL code to the subfield in "<code>" in the field "<tag>". If there already is a modifying agency in the "<tag>.<code>", this adds another agency ISIL code. | |
| replaceModifyingAgency "<tag>.<code>"
Example:replaceModifyingAgency "040.d"
|
Adds the modifying agency ISIL code to the subfield in "<code>" in the field "<tag>". If any modifying agencies already exist in the "<tag>.<code>", all of them are replaced. | |
| Split subfields | splitSubField "<tag>.{ind1,ind2}.<code>.<delimiter>" to "<tag>.{<ind1>,<ind2>}.<code>" addSeq "<code>"
Example 1:splitSubField "866.a.;" to "555.{0,0}.a" addSeq "8"
Example 2:splitSubField "555.a. – " to "859.{0,0}.a" addSeq "8"
Example 3:splitSubField "859.a.\\\\."
Example 4:splitSubField "999.a.;" to "555.a" addSeq "8"
|
Il tag è obbligatorio.
Gli indicatori (di campo) sono facoltativi. Poiché la suddivisione avviene a livello di Sottocampo, il codice è obbligatorio. Il delimitatore può essere qualsiasi stringa. Se il delimitatore non esiste, l'intero Sottocampo viene copiato come prima (e unica) occorrenza, e la sequenza viene aggiunta. Il componente to è opzionale. Se specificato, vengono create più occorrenze di to tag.code, ciascuna con i dati fino al delimitatore. Veda gli esempi 1 e 2. Se il componente to non è specificato, il Sottocampo viene suddiviso nel Sottocampo aggiuntivo nello stesso campo come mostrato nell'esempio 3. Il componente addSeq è facoltativo. Non è rilevante se il componente to non è specificato. Quando si specifica addSeq, il Sottocampo con una sequenza verrà aggiunto come nell'Esempio 1; e se il Sottocampo esiste già nel campo originale, una sequenza (preceduta da un punto) verrà aggiunta a quel campo come nell'Esempio 2. |
|
Remove duplicate subfields |
correctDuplicateSubfields "<tag>" "<code>" Ad esempio: Removes duplicate subfields x, y and z from fields 610 and 630. rule "Remove duplicates" priority 1 when (TRUE) then correctDuplicateSubfields "610,630" "xyz" end |
Corrects duplicate subfields (for instance, subfields with the same code AND the same value) by keeping the first occurrence and removing the others from the current record according to the fields and subfields that were passed as parameters. Potrebbe voler usare recordHasDuplicateSubfields per creare il Set da fornire alle Sue Regole di normalizzazione che usano correctDuplicateSubfields. See Example 6 for more information. For deduplication of subfields with different values, see:How to remove all but one of several similar subfields in the same field in MD Editor. |
|
Move subfields |
moveSubfieldsToEndOfField "<tag>" "<code>" Ad esempio: Moves subfields 9 and 2 to the end of field 650. rule "Move subfields to end of field" priority 1 when (TRUE) then moveSubfieldsToEndOfField "650" "92" end |
Sposta la prima occorrenza di ogni sottocampo alla fine del campo e rimuove tutte le altre occorrenze dello stesso sottocampo. Se viene specificato più di un Sottocampo, essi sono posizionati alla fine nella stessa sequenza indicata nella regola. In questo esempio, Sottocampo 9 è posizionato alla fine, seguito da Sottocampo 2. Note that the if statement is not supported with the moveSubfieldsToEndOfField action. |
|
Corregga il campo duplicato per il recordcorrente |
correggiCampiDuplicati "{fields}" Esempio: correggiCampiDuplicati "610,630,650" |
Questa azione accetta un parametro, campo, che contiene valori di campo separati da virgole, come 610, 630, 650. Questa azione corregge il campo duplicato per il record corrente in base al campo passato come parametro. Questa azione può essere utilizzata solo per identificare e correggere i dati duplicati trovati tra più istanze dello stesso campo. |
|
Trova il campo duplicato (Indication Rules; see Working with Indication Rules) |
recordHaCampiDuplicati "{fields}" Esempio: recordHasDuplicateFields "610,630,650" |
Questa azione accetta un parametro, campo, che contiene valori di campo separati da virgole, come 610, 630, 650. Questa azione può essere vera o falsa. Restituisce true se sono stati trovati campi duplicati per il record corrente in base ai campi passati come parametro. Questa azione può essere utilizzata solo per identificare e correggere i dati duplicati trovati tra più istanze dello stesso campo. |
Wildcards and Special Characters
While the use of regular expressions in Alma Normalization Rules is not currently fully supported, some regular expressions can be used – for examples of these, see Alma Normalization Rule Examples.
Il separatore Sottocampo ($$) non può comparire in nessun punto della regola, incluso il nome della regola.
Un carattere cancelletto (#) all'inizio di una riga indica che il resto della riga è un commento e viene ignorato durante l'elaborazione della regola.
The hash character (#) is not treated as a space by the normalization rules function replaceControlContents. The hash (#) is not a wild card and is not supported by this function.
L'asterisco (*) viene utilizzato per abbinare qualsiasi stringa, inclusa una stringa di lunghezza zero. For example,"<tag>.<*>.<value>" applies to all the subfields in the tag <tag> that have the value <value>.* is "greedy", so it matches as many characters as possible in the string. Ad esempio: se Lei ha una stringa "a b c b d b e", il Modello "b*b" corrisponde a "b c b d b", non solo a "b c b".
Gli indicatori vuoti (di campo) (ma non campo o sottocampo) sono indicati da un trattino (-). For example,"<tag> {-,<ind2>}" returns all the fields where the MARC tag is <tag>, the first indicator is not defined, and the second indicator is <ind2>.
Se il testo di un Sottocampo termina con un punto, utilizzare quattro barre rovesciate per corrispondere al punto. Ad esempio:
Le virgolette doppie possono essere utilizzate solo nelle condizioni. To use double quotation marks as part of a condition, use single quotation marks to enclose text in the rule (') instead of double quotation marks ("). This way you can use double quotation marks inside the text following a double backslash (\\).
Le date ebraiche possono essere utilizzate in condizioni (solo). (L'ebraico si legge da destra a sinistra, quindi le doppie barre rovesciate nell'esempio seguente sono effettivamente prima delle virgolette doppie.)
- I caratteri jolly non possono essere utilizzati come primo carattere di una condizione o di un valore.
- To use a literal backslash (\), escape it with another backslash:\\.
- Utilizzare quattro barre rovesciate (\\\\) per eseguire l'escape di un punto quando è l'ultimo carattere della stringa. Quando il punto è seguito immediatamente da un altro carattere, non sono necessarie quattro barre rovesciate (come in addField "907.a.F.L.T\\\\."). Tuttavia, è prassi migliore utilizzare sempre le quattro barre rovesciate nelle Regole di normalizzazione per garantire i risultati desiderati più coerenti. Veda i seguenti esempi.
- Come indicato sopra, se si utilizza una doppia virgoletta in una condizione che è eseguita con escape tramite virgolette singole, o una virgoletta singola in una condizione che è eseguita con escape tramite virgolette singole, è necessario eseguire un ulteriore escape della doppia virgoletta o della virgoletta con una doppia barra rovesciata.
- If the pipe symbol is part of the condition, use four backslashes to escape it, for example:removeField "866" if (exists "866.8.0\\\\|99"). Questo è necessario solo quando si utilizza un simbolo pipe nella condizione.
Example: Using the Period in a Normalization Rule with replaceContents
Example record with periods:
245 00 $$a Feminist literary theory. : $$b un lettore / $$c curato da Mary Eagleton.
246 0# $$a F.L.T.
Regole di normalizzazione per il record di esempio sopra:
Veda la figura sottostante per gli esempi prima e dopo.
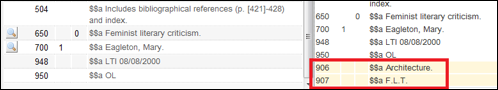
Example: Using the Period in a Normalization Rule with addField
Di seguito è riportato un esempio di record a cui è necessario aggiungere i punti:
906 $$a Architettura.
907 $$a F.L.T.
Di seguito sono riportate le Regole di normalizzazione per il record di esempio sopra, utilizzando la best practice di includere sempre le barre:
Veda la figura sottostante per gli esempi di record prima e dopo.
Normalization Rule Examples
For a list of over 100 normalization rule examples and other normalization rule documents, see Alma Normalization Rule Examples.
For more information on creating normalization rules for bibliographic records in XSL format, see Alma XSL Normalization Rule Examples.
Alma supporta fino alla versione XSL 3.0.
Page tags: article:topicproduct:almacontent:Documentationlang:englishactionsRulesyntaxnormalization rule syntaxconditionselements
